Your models.
Your hardware.
Your endpoint.

I take open-weight vision and multimodal models from raw data to a production endpoint on infrastructure you control. Your data stays inside, and the code and weights stay yours.
Book a call See the work 30 minutes, no slides.
Gabriel Cicotoste

Trusted by teams at

GE21 Geotecnologias OmniHunter ObotX MyArchitectAI North of Zero Kexxu Robotics

Your data leaves the building

Every request ships your images and documents to someone else's servers, under someone else's terms.

The bill grows with success

Per-token pricing punishes you for using the product more. Self-hosted inference costs what the hardware costs.

The model is not yours

You cannot fine-tune it, pin a version, or take it with you when the vendor changes the pricing.

01

Pretraining

Representations learned from your raw images, no labels required. Self-supervised training in the I-JEPA line, and backbones like DINOv3 carried into domains they were never trained on, multi-spectral among them.

See the I-JEPA build
02

Finetuning

Open weights adapted to your data. LoRA and QLoRA on vision-language models, segmentation and detection, from satellite imagery to surround-camera video, on the VRAM you actually have.

See it in the work
03

Inference & Serving

Your model, your machine, your URL. An OpenAI-compatible endpoint on your own hardware, vLLM picked automatically on NVIDIA GPUs, plus streaming pipelines that keep long video inside a real memory budget.

See SursumAI
01

Scope

We start from the constraints that decide everything else: your data, your hardware, your latency budget and what can never leave your network.

02

Adapt

The right model is picked and trained on your data, pretrained from scratch or finetuned from open weights, then measured against the baseline on your own examples.

03

Ship

It goes live behind an endpoint you control, running on your machines, with the code and weights handed over to you.

Audit

A focused read on whether open weights win for your case.

  • Open-weight candidates benchmarked on your data
  • Latency and cost projection on your hardware
  • A clear go or no-go recommendation
Start with a call

Production

Hardened, documented and handed over to your team.

  • Batching and streaming for real traffic
  • Runbooks, monitoring and versioning
  • Code and weights handed over
Start with a call

AI Startups

Teams that need a vision model working now, without building an ML department first.

Sensitive Data

Where the data cannot leave the building, and an external API is not an option.

Geospatial & EO

Multi-spectral segmentation, cloud removal and land-cover analysis at scale.

Robotics & 3D

Bird's-eye-view perception, real-time depth and reconstruction from video.

SursumAI: Self-Hosting Models

Your model. Your machine. Your URL. Deploy open-weight and custom models on your own hardware and get an OpenAI-compatible endpoint. No terminal, Docker, or GPU knowledge needed. Picks vLLM automatically on NVIDIA GPUs.

Self-Hosting vLLM Model Serving
Visit sursumai.pages.dev

DA3-Streaming: Depth in Real Time

Streaming pipeline that lets Depth Anything 3 run on long video sequences and large-scale scenes under tight CPU/GPU memory budgets, chunking frames and carrying state across chunks for stable online inference.

Depth Estimation Streaming Inference Memory Efficiency
View on GitHub

Digital Twinning: Images to Mesh

Two 3D reconstruction pipelines compared on the same multi-view capture: SAM3 segmentation feeding COLMAP sparse and dense MVS, against 3D Gaussian Splatting converted to mesh with SuGaR. Both end in textured geometry.

3D Reconstruction SAM3 + COLMAP Gaussian Splatting
View on GitHub
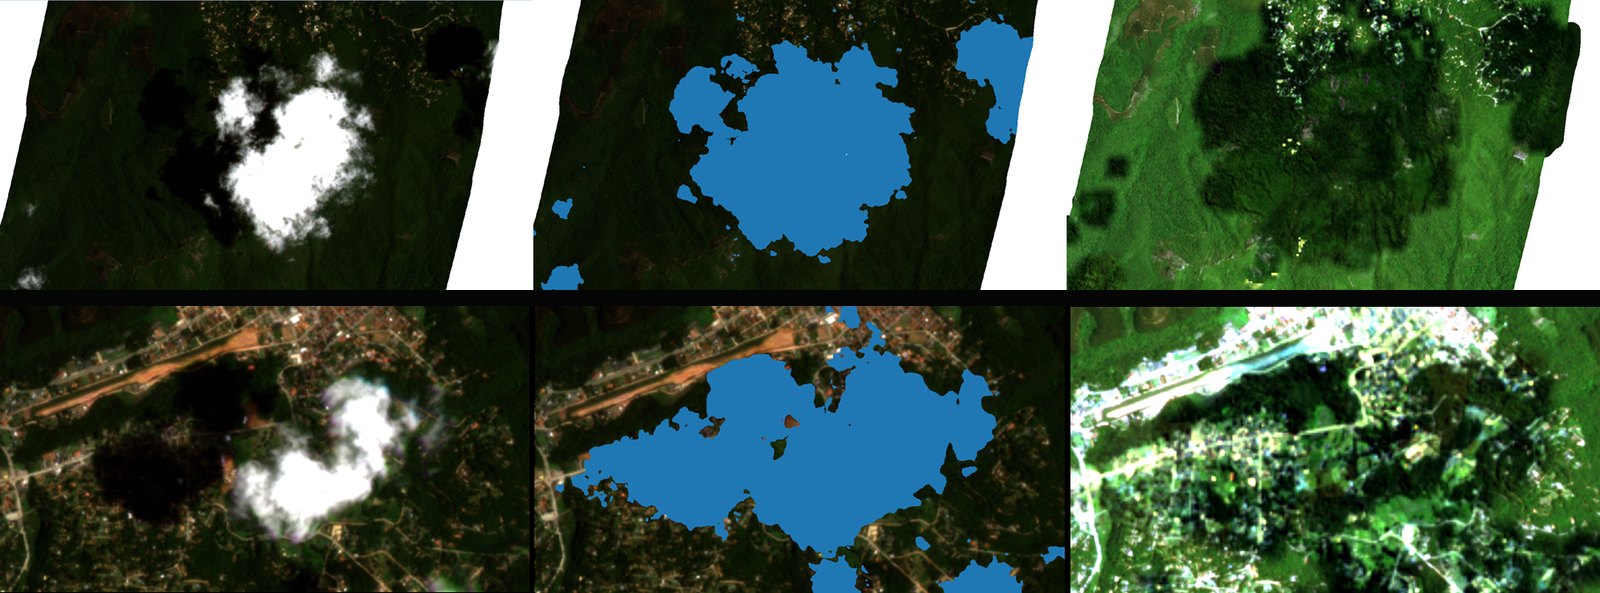
cloudpurge: Clouds Out of Planet Imagery

cloudpurge: Clouds Out of Planet Imagery

Stacks cloudy Planet imagery over clean Sentinel-2 of the same place. Detects the clouds, opens a hole through them and the surrounding haze, matches brightness by histogram, and composites with a feathered edge so the seam disappears.

Remote Sensing Cloud Masking CLI
View on GitHub

Tesla BEV Cam Clone

Bird's-eye-view perception system replicating Tesla FSD's surround-camera fusion pipeline for real-time vehicle and lane reconstruction.

BEV Perception Camera Fusion PyTorch
View on GitHub
Metric 3D built from Depth Anything, with 3D vehicle detection.
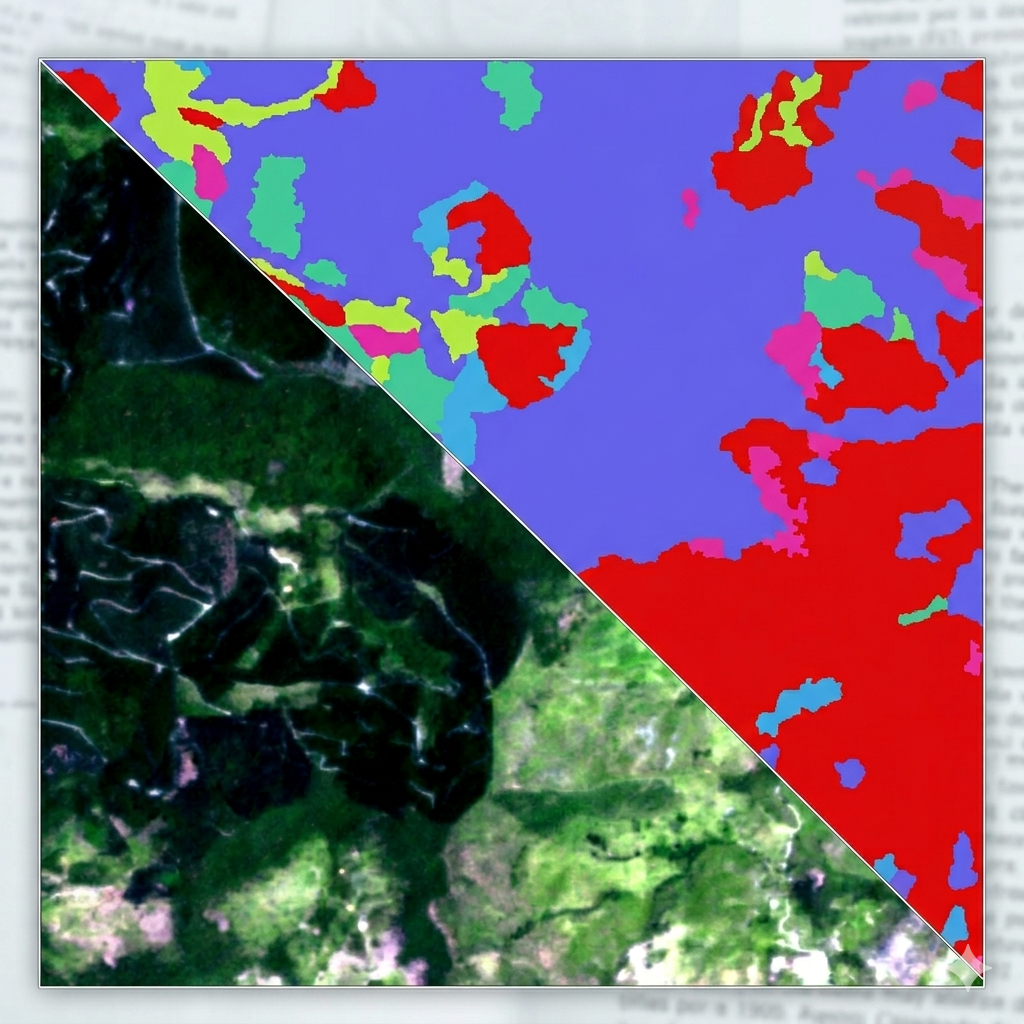
Satellite multi-spectral segmentation

Privhti EO: Satellite Segmentation

Multi-spectral semantic segmentation of satellite imagery for Earth Observation, built for Privhti EO's geospatial intelligence platform.

Remote Sensing Multi-Spectral Segmentation
View on GitHub

KlipMind

Local video summarizer that runs entirely on-device. No data leaves your machine. Extracts key moments and generates structured summaries from any video file.

On-Device AI LLM Video Understanding
View on GitHub
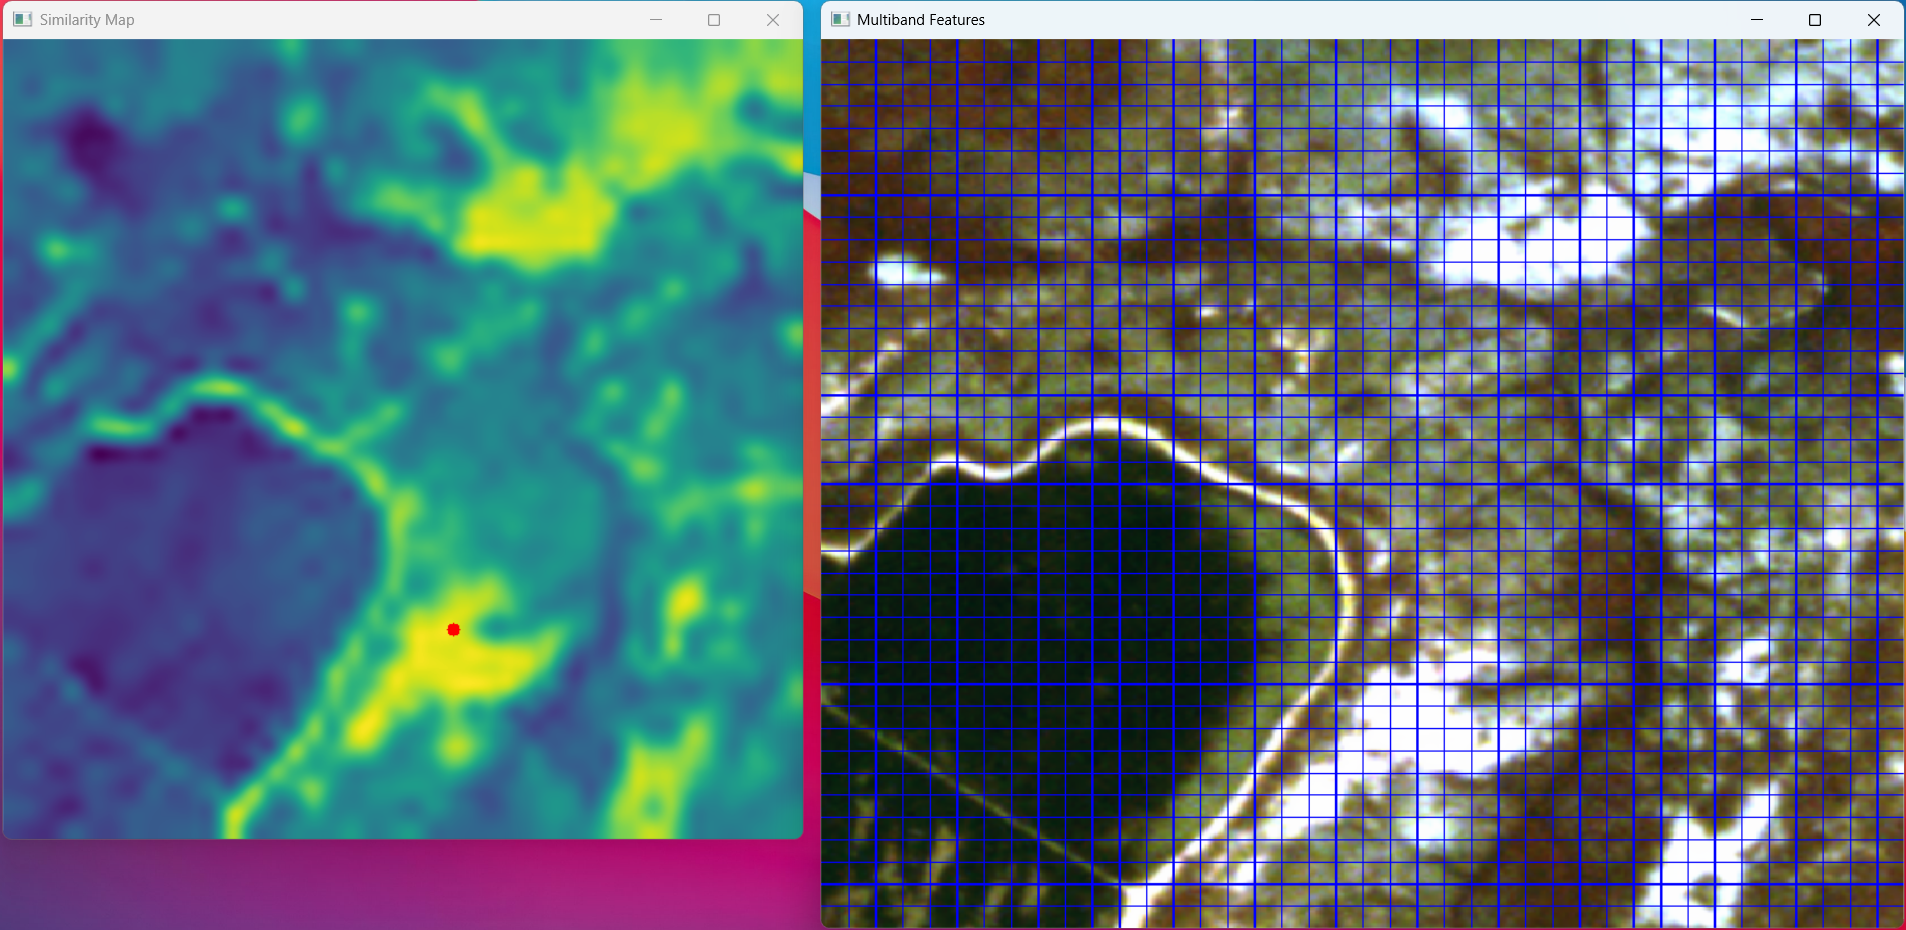
DINOv3 multi-spectral similarity maps

DINOv3 Multi-Spectral Similarity Maps

Adapting DINOv3 self-supervised features to multi-spectral imagery for dense similarity mapping, enabling zero-shot land-cover analysis without labeled data.

Self-Supervised DINOv3 Similarity Maps
View on GitHub
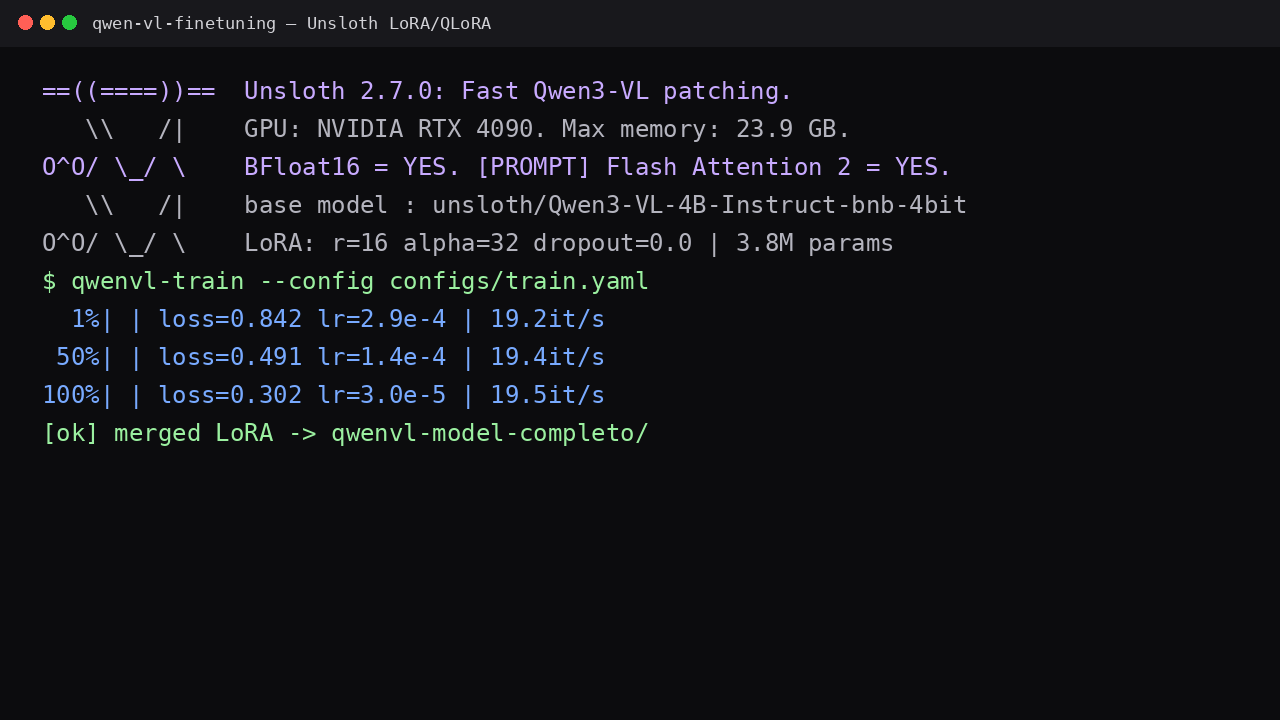
Qwen3-VL LoRA fine-tuning terminal

Qwen3-VL Fine-tuning

CLI for fine-tuning and fast inference of Qwen3-VL with LoRA/QLoRA, adapting open-weight vision-language models to domain data with minimal VRAM.

LoRA/QLoRA Qwen3-VL Fine-tuning
View on GitHub
Gabriel Cicotoste

Gabriel Cicotoste

Deep Learning Engineer | Pretraining, Finetuning, Inference & Serving Vision Models

Brasil · 4,590 followers

Do I need my own GPU?

No. Smaller models run on CPU through llama-server. If you have an NVIDIA GPU, SursumAI picks vLLM automatically for far higher throughput.

Does my data leave my infrastructure?

No. Training and inference run on your machines. I work inside your environment and nothing is uploaded to a third party.

Who owns the code and the weights?

You do. Everything built in the engagement is handed over at the end, including training code, serving code and model weights.

How do open weights compare to a closed API?

If a closed API covers your case and the data is not sensitive, use it. Open weights win when data cannot leave, when usage is heavy enough that per-token pricing hurts, or when you need to fine-tune and own the model.

Which models do you work with?

Vision and multimodal models: Qwen-VL, DINOv3, Depth Anything, SAM, Prithvi, YOLO, and whatever fits the problem.

How do we start?

Book a 30 minute call. We go through your data, hardware and constraints, and I tell you whether open weights make sense for your case.

Have a model that should be in production by now?